Rustock node, six months later
I started working on the Rustock node to try to improve rskj's snap sync protocol. Rustock is a Rust implementation of the Rootstock network node — it lives at rustock.dev, this website — and it's a project begun by Javier Álvarez Cid-Fuentes, which I am now the one pushing forward.
I had two main reasons to pursue this project: contributing to the Rootstock network and, at the same time, getting into a serious AI coding project using the most modern models. The big advantage of doing the research on Rustock rather than on rskj has to do with development cycles and with motivation. rskj is the codebase that fixes Rootstock's consensus — 99% of the network's nodes run rskj — which means its core developers must be extremely cautious about changing the node. The decision is a personal one: waiting years to see something implemented takes nerves of steel, and after a few months I have usually moved on to a project that motivates me more. The waiting kills me.
Working on Rustock gave me the chance to see my experiments running on the network without the long wait. Having a second implementation of the same consensus also gave me something I did not have before: the ability to run comparative performance tests, and to carry back to rskj the improvements that are concise, self-contained, and at the same time deliver the largest efficiency gains.
When I first looked at the Rustock node I understood what "experimental" really meant. There were many basic functions that had never been exercised and simply did not work. Other functions, the moment you scratched the surface, turned out to skip critical verifications and to carry a long list of security holes. The models that built Rustock put the emphasis on passing the tests, but the tests did not cover enough adversarial cases.
I started the slow job of fixing each problem. But at the same time I realized that modern models like Claude Opus 5 could review the code far faster than I could, and my time for programming is very limited: my main job, for many years now, has been research. So I decided to continue the experiment with extreme vibe coding: I set myself the rule of never, ever looking at the source code. I would correct and steer the agent on algorithms, and shore up its gaps about the internals of Rootstock consensus — but never look at the code. Treat it like assembly language.
I set some ground rules for code generation: test cases and adversarial thinking. Write documents explaining the algorithms and comparing them against rskj for every new piece of functionality. Nothing exotic. My role was to step in four or five times a day, answer the model's questions, ask it to continue, without stopping, weekends included. The code must go on.
The goal: snap sync, block pruning, header-only sync, merged mining, an immutable header database (the "freezer"), a trie garbage collector, a segmented database for fast re-execution, and every existing RPC method. Twenty-two days uninterrupted, around 400 commits, roughly eighteen a day. This would have been impossible without AI — not because humans cannot write this code, but because a team of five programmers working in parallel cannot easily coordinate the deep, cross-cutting changes these features require. Merging the various components alone would have taken weeks or months, between dependencies, interference and incompatibilities.
Where the node stands today: ten crates, around 174,000 lines of Rust, some 2,600 tests, 70 RSKIPs implemented, and 121 written-up findings about where rskj's behaviour and its specification part ways. All of that — the documentation, the architecture notes, the JSON-RPC reference, the compatibility analysis and a live status page for a node following mainnet — is at rustock.dev.
Below is what was implemented, what each component buys, and what each one is good for.
Security hardening: the part nobody asks for
This is where most of the early time went, and it is the least glamorous item on the list. Rustock came with many vulnerabilities. The original agents that built its foundations paid no attention to defending the protocol against an adversary: messages were trusted, sizes were unbounded, a peer that sent garbage was sidelined for a few minutes and then welcomed back.
Snap sync: joining the chain without replaying it
I started with my project goal: state snapshot synchronization. This is the continuation and enhancement of the work started by Julián Len, Patricio Gallardo, Iago Lluque and Javier Álvarez Cid-Fuentes. A node joining the network has two options: execute every transaction from genesis — correct by construction, and days of work — or download the state trie directly and check it against a state root it trusts for other reasons. Snap sync is the second.
What is given up is the re-execution of history, not the verification of it. The client walks the header chain back from the checkpoint a peer offers, verifying merged-mining proof of work and every consensus rule on each header, and only then downloads state under that header's state_root, proving every chunk as it arrives. A peer that invents a checkpoint has to have mined it. Both sides are implemented, and both wire dialects: Rustock serves and reads its own chunk format, and serves and reads rskj's.
Headers that carry their uncles
Snap sync work revealed that the Rootstock wire protocol was not optimized for header-only synchronization. A detail of Rootstock consensus turned into one of the more consequential pieces of work. In RSK, total difficulty advances by the trunk block's difficulty plus the difficulty of the uncles it references. A node that downloads only headers therefore cannot compute the chain's accumulated work: the uncle headers live inside bodies, which it does not have. That single fact blocks header-only sync, blocks an exact difficulty comparison during snap sync, and makes a pruned node unable to recompute its own chain's weight.
The fix needed a new version of the wire protocol: rsk/63.
Header-first (ascending) sync
Snap sync, as shipped, walks headers downward from the peer's checkpoint until it reaches ground the node already holds. On a fresh node that is genesis — so the walk downloads every header anyway. Measured on mainnet, that walk is 92.4% of a snapshot sync. What snap sync actually saves against a full sync is bodies and execution, not headers.
That observation suggested inverting the shape: walk up from genesis to the checkpoint first, verifying proof of work and every body-independent consensus rule, and only then ask for state.
On raw speed the two shapes come out within a few percent of each other on a single peer, which is what the design note predicted — the argument for ascending was never single-peer throughput. What it buys is elsewhere, and it is substantial: the chain's total difficulty comes out exact rather than as a lower bound, the sync becomes resumable across restarts.
The freezer: an immutable header database
A header lives in RocksDB under its hash. Hashes are uniformly distributed, so 192 consecutive blocks live in 192 unrelated places — and 192 consecutive headers is exactly the unit a syncing peer asks for. Serving nine million headers means answering roughly 48,000 such requests, each one 192 independent point lookups, each reading a whole SST block (and often an index block above it) to return 1.1 KB. Measured: 7.1 KB of disk read to deliver 1.1 KB of header.
The first fix was to stop issuing those lookups serially. Running them through a 16-deep thread pool raised throughput sevenfold. That is the whole design argument in one measurement: concurrency hides latency, it does not reduce the bytes read. Only the layout does.
So the freezer moves settled headers out of the B-tree into append-only files with a fixed-width ten-byte index, addressed by arithmetic rather than by lookup: a run of 192 consecutive headers becomes a run of adjacent bytes, one read. Headers are the right thing to attack this way — they are what a syncing peer asks for most, they are immutable once settled, and they are read in runs. The freezer archives the uncle headers alongside the trunk, in the same format, and that turned out to matter as much as the read win.
Block pruning
Deleting history is easy; knowing how much you are allowed to delete is not. Rootstock exposes precompiles that read attributes of blocks up to 4,000 back, so executing a block at height h may read from h − 4000. After a 4,000-block reorg the node re-executes from head − 4000, and executing that block may reach a further 4,000 back. The shallowest safe retention is therefore 8,000 blocks — and that is a floor. Pruning removes all prior blocks, except from the genesis which is always retained. Pruning also has to be announced, which is the other half of what rsk/63 adds.
Trie garbage collector
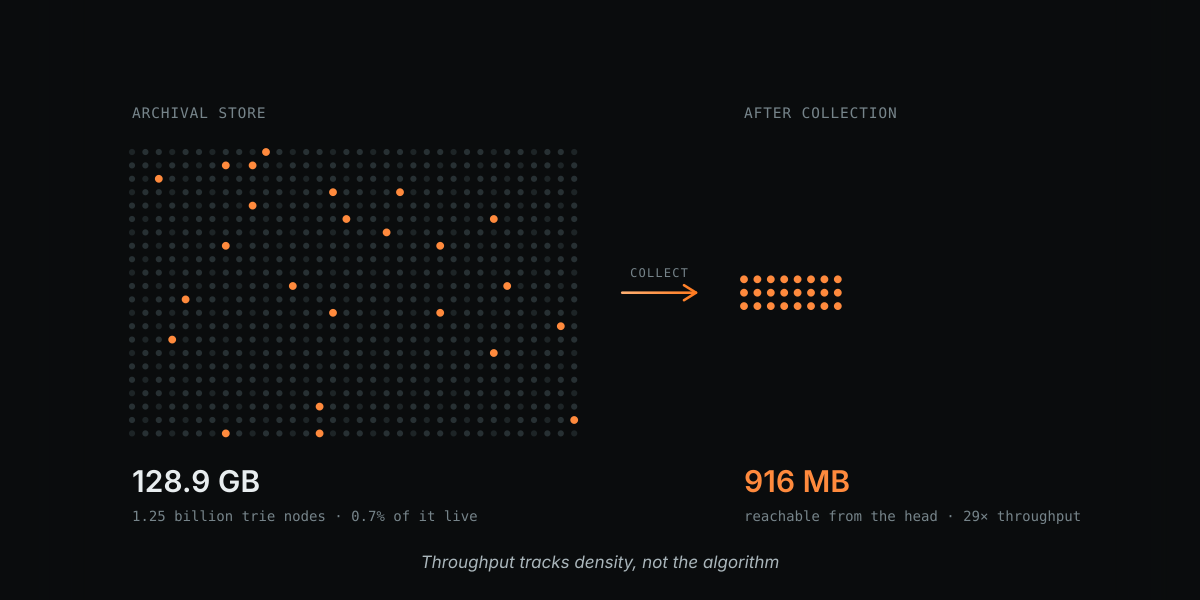
A node that executes every block writes a new version of every trie node it touches. Nothing is updated in place, so the store accumulates every historical state while only a small part is reachable from the current head. On Rustock's RSK mainnet database at block 9,230,008: 1.25 billion trie nodes, 128.9 GB on disk, and 916 MB reachable from the head's state root. The live fraction is 0.7%. Roughly 99% of the trie store is dead history.
Reclaiming that without a reference count on every node, and without a deletion pass proportional to the number of dead entries, is what the epoch collector does: the store is a fixed-size ordered list of epoch databases, each holding a contiguous slice of write history, and collection copies the live set forward and drops the oldest epoch whole. Content addressing is what makes it work — an entry's key is the hash of its value, so a node can be copied between databases without any referrer changing.
The payoff is not only the disk space, it is the density. Throughput against a trie store tracks how much of it is live. Keeping only the active trie increases the throughput 29x!
Segmented database for fast re-execution
Re-executing the chain to check that a change has not broken consensus backwards is a read-bound job, and the reads are the worst kind: a trie descent issues dependent random reads, so the device sees one outstanding request at a time. The store makes it worse, because content addressing scatters a block's working set uniformly across 131 GB.
Throughput tracks density, not the algorithm. A segmented store is the same data reordered by block number instead of by hash: each segment holds exactly the nodes some block range touches, so density inside a segment is ~100% and the working set stays resident.
Supply conservation: rejecting blocks that create rBTC
This is an implementation of one of the defence-in-depth proposals. The RSK peg is backed 1:1 by bitcoin: the Bridge holds the entire supply, and a peg-in transfers value out of the Bridge's balance rather than creating it. It follows that no block may increase the total of all account and contract balances. A node that enforces this catches any bug that mints rBTC, no matter where it lives or how it was reached.
Merged mining, and the long tail of a real node
Rustock builds RSK blocks, hands them to mining software through the mnr_* JSON-RPC namespace, and completes them from the Bitcoin solutions submitted back — so a second implementation can take part in securing the chain, not just follow it.
Come help
Rustock is an experimental prototype. It should not be used in production, it has not been audited in depth beyond the one audit described above, and it will break. That is the honest label on the box.
But the case for a second Rootstock node implementation does not depend on this one being finished. A network where 99% of nodes run the same code has a single point of failure, and no way to tell a consensus bug from consensus itself. The most useful results in this article came from the gap between two implementations — measurements, protocol details and design choices that are simply not visible from inside a single client. Writing a second node is also how the knowledge about Rootstock consensus gets extracted from one codebase and written down — the RSKIPs, the comparison documents, and the specifications in this repository exist because something had to be reimplemented from them.
So: run it, break it, and tell me how. Start at rustock.dev — the quickstart is three commands, and the status page shows a node following mainnet right now. Read the design documents and tell me where the argument is wrong — several of them are proposals rather than descriptions, and the ones written as specifications are written that way so rskj can take them. File an issue, send a pull request, or port one of these components back to rskj, which is where most of them were always aimed. I post what the node is doing as it happens at @RustockDev.
rustock.dev · github.com/SergioDemianLerner/rustock · @RustockDev